Crawled / Discovered – currently not indexed on a programmatic site: triage by template
On a programmatic site, not-indexed pages come in groups. Google's own definitions, how to export and group the URLs by template, and what to do with each group.
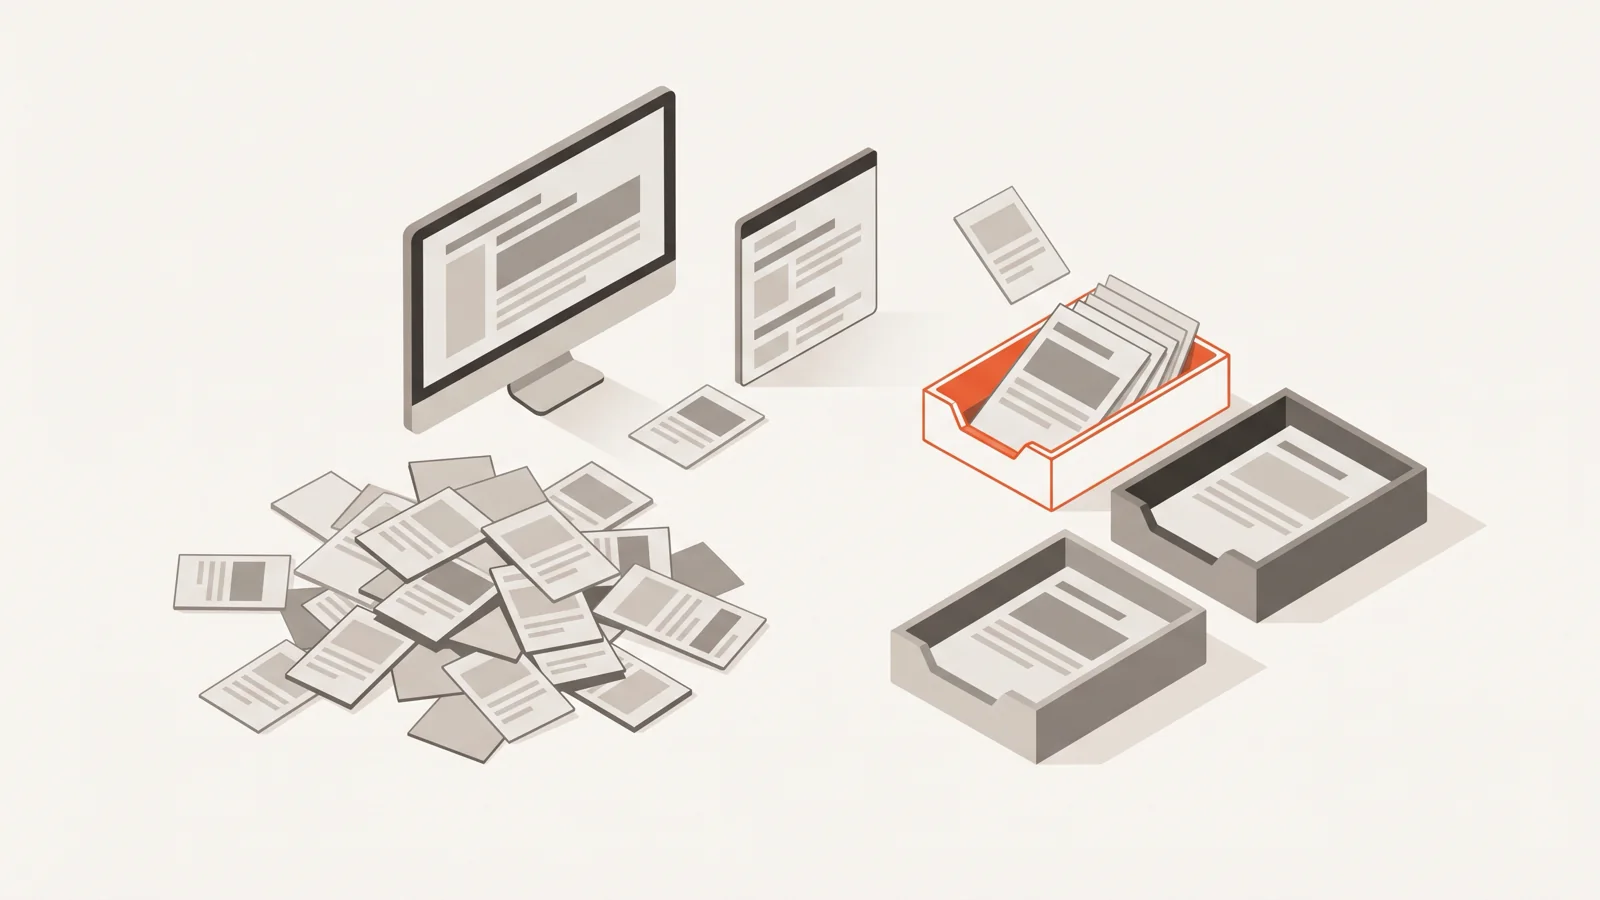
"Crawled – currently not indexed" and "Discovered – currently not indexed" mean different things, and on a programmatic site they almost always show up in groups that share a URL template. Crawled means Google fetched the page and chose not to index it, which is a quality or duplication decision. Discovered means Google knows the URL but hasn't fetched it yet, which is about scheduling and crawl capacity. So don't fix them URL by URL. Export the affected URLs, group them by template and query-parameter pattern, and give each group one action: improve it, consolidate it, keep it out of Google on purpose, remove it, or leave it alone.
What the two statuses mean, in Google's words
Google's Page indexing report help page defines them like this (Search Console Help, Page indexing report):
Crawled – currently not indexed: "The page was crawled by Google but not indexed. It may or may not be indexed in the future; no need to resubmit this URL for crawling."
Discovered – currently not indexed: "The page was found by Google, but not crawled yet. Typically, Google wanted to crawl the URL but this was expected to overload the site; therefore Google rescheduled the crawl."
The same page sets a baseline that's easy to forget when you're staring at a chart of 20,000 excluded URLs: "You should not expect all URLs on your site to be indexed, only the canonical pages" (Page indexing report). Google's crawl budget guide puts it the same way: "not every page that is crawled will necessarily be indexed. After crawling, each page must be evaluated, consolidated, and assessed to determine its suitability for the index" (Google, crawl budget management).
Two related statuses usually sit next to these on programmatic sites and belong in the same triage:
- Duplicate without user-selected canonical: the page is a duplicate, doesn't declare a canonical, and "Google has chosen the other page as the canonical for this page".
- Duplicate, Google chose different canonical than user: you declared this page canonical, but "Google thinks another URL makes a better canonical" (Page indexing report).
Why programmatic sites get hit
A programmatic site produces pages from data: one template, thousands of rows. That's efficient, and it's also why one weakness in the template or the data repeats on every page. These are the causes that matter at that scale.
Quality and sameness (mostly "Crawled")
If 5,000 location pages say the same 80 words with the city name swapped, Google crawls a few, sees little to distinguish them, and indexes some or none. At the extreme end, Google's spam policies define scaled content abuse as "when many pages are generated for the primary purpose of manipulating search rankings and not helping users", with examples such as pages generated "without adding value for users" (Google spam policies). Most programmatic sites aren't anywhere near that line, but the direction of travel is the same: the less each page adds, the more of them get crawled and left out.
Duplication (Crawled, or the two Duplicate statuses)
Typical sources: the same job posted in three cities, a product reachable under two category paths, sort orders and filters creating new URLs for the same list, trailing-slash and case variants. Google's guide on crawl budget names this as the factor you control most: "If many of these URLs are duplicates, or you don't want them crawled for some other reason (removed, unimportant, and so on), this wastes a lot of Google crawling time on your site. This is the factor that you can positively control the most" (crawl budget management).
Crawl capacity (mostly "Discovered")
Google's crawl budget guide is written for three kinds of site, and two of them describe a typical programmatic site: "Medium or larger sites (10,000+ unique pages) with very rapidly changing content (daily)" and sites "with a large portion of their total URLs classified by Search Console as Discovered – currently not indexed" (crawl budget management). A job board fits both. Our own test site, jobxdubai.com, is a job board where listings are added and expire every day: our 7 October 2026 crawl fetched 37,218 pages, and its jobs sitemap alone lists 30,729 URLs.
The same guide says Google's crawl capacity for a site goes down when the site slows down or returns 5xx or 429 errors (crawl budget management). A slow server-rendered template can therefore keep pages in "Discovered" even when nothing is wrong with their content.
Weak internal linking (both)
Programmatic pages are often reachable only through deep pagination or the sitemap. A job on page 40 of a listing, five or more clicks from the homepage, gets little internal link weight and is crawled late. If Google can only find a URL through the sitemap, that's a weak signal of its importance.
Parameter URLs (both)
Faceted navigation creates a near-infinite set of URLs. Google's documentation on faceted navigation describes the result: crawlers "will typically access a very large number of faceted navigation URLs", and "if crawling is spent on useless URLs, the crawlers have less time to spend on new, useful URLs" (Google, faceted navigation). Parameter URLs pile up in "Discovered" and push real pages back in the queue.
Export the URLs and group them by template
Getting the URLs out of Search Console
In Search Console, open Pages (the Page indexing report), then click a row in the "Why pages aren't indexed" table to see its URLs. Export from the details page. On a big site, note the limit: the list "does not necessarily show all URLs with that issue, and is limited to 1,000 rows" (Page indexing report).
Three ways to see past 1,000 URLs:
- Split your sitemaps by template. The report can be filtered by All known pages, All submitted pages, Unsubmitted pages only or one specific sitemap (Page indexing report). With one sitemap per page type (
jobs.xml,companies.xml,salaries.xml), each filter gives you a per-template chart and its own 1,000-row sample. This is the cheapest change on this list and it keeps paying off, because the per-sitemap chart becomes your tracking dashboard. - Use the URL Inspection API for bigger samples. It allows 2,000 queries per day and 600 per minute per property (Search Console API usage limits), so 10,000 URLs take five days.
- Treat 1,000 rows as a sample. For grouping, you don't need every URL. If 900 of the 1,000 exported URLs are
/jobs?page=&sort=, you know where the problem is.
Grouping the export
Collapse each URL to a template key: keep the first path segment, replace IDs and slugs, and keep the sorted parameter names (not values). This Python script does that for one or more exported CSV files. It uses the same rules SEOFix uses for template grouping:
# group_by_template.py: python3 group_by_template.py crawled.csv discovered.csv
import csv
import re
import sys
from collections import Counter
from urllib.parse import urlsplit, parse_qsl

HEX_ID = re.compile(r"^[0-9a-f]{16,}$")
UUID = re.compile(r"^[0-9a-f]{8}-[0-9a-f]{4}-[0-9a-f]{4}-[0-9a-f]{4}-[0-9a-f]{12}$", re.I)


def template(url: str) -> str:
    parts = urlsplit(url)
    segs = [s for s in parts.path.split("/") if s]
    if not segs:
        key = "/"
    else:
        out = [segs[0]]
        for s in segs[1:]:
            if s.isdigit() or UUID.match(s) or (HEX_ID.match(s) and re.search(r"\d", s) and re.search(r"[a-f]", s)):
                out.append("[id]")
            elif "-" in s or re.search(r"\d", s) or len(s) > 24:
                out.append("[slug]")
            else:
                out.append(s)
        key = "/" + "/".join(out)
    params = sorted({k for k, _ in parse_qsl(parts.query, keep_blank_values=True)})
    if params:
        key += "?" + "&".join(f"{k}=" for k in params)
    return key


counts = Counter()
for path in sys.argv[1:]:
    with open(path, newline="", encoding="utf-8-sig") as f:
        for row in csv.reader(f):
            url = next((c for c in row if c.startswith("http")), None)
            if url:
                counts[template(url)] += 1

for key, n in counts.most_common():
    print(f"{n:>7}  {key}")
Output looks like this:
    612  /jobs/[slug]
    241  /jobs?page=&sort=
     88  /company/[slug]
     40  /jobs?tag=
     19  /salaries/[slug]
Run it separately on the Crawled export and the Discovered export. The same template showing up in both lists is common, and the two halves usually need different actions.
What to look at for each group
Before deciding, open five or six sample URLs from each group and note:
- Status and indexability: does it answer
200, is it self-canonical, does it carrynoindex? - Unique content: how many words are specific to this page rather than the template? Does the title differ from its siblings?
- Links in: how many internal pages link to it, and how deep is it?
- In the sitemap? Should it be?
- Demand: did the template's indexed pages get impressions in Search Console? If the indexed half of a template gets no traffic either, the unindexed half won't.
The decision table
| What the group looks like | Status it usually has | Action |
|---|---|---|
| Real pages, distinct data, but thin text or near-identical titles | Crawled | Improve the template: add the fields that make each page different, differentiate title and description |
| Real pages, fine content, deep in pagination or only in the sitemap | Discovered | Link them: from hubs, category pages and related items; keep them in the sitemap |
| The same content under several URLs | Crawled, Duplicate | Consolidate: one canonical URL, rel="canonical" or a redirect from the others, internal links to the canonical |
| Filters, sorts, tracking parameters, internal search | Discovered, Crawled | Keep out on purpose: noindex or canonical to the clean URL, drop from sitemap, stop linking; later robots.txt |
| Expired, deleted or empty-result pages | Crawled, Soft 404 | Remove: 404 or 410, drop from sitemap and internal links |
| A small number of pages with no search demand | Either | Leave it. Not every page needs to be indexed |
Improve (worth indexing, Crawled)
Compare an indexed page and an unindexed page from the same template, side by side. The differences are usually in data, not prose: salary range, requirements, company details, map, related listings, last-updated date. Add fields that really vary per page. Then check that the title and meta description contain the distinguishing values. If 3,000 job pages share the title "Accountant job | Brand", Google sees 3,000 near-copies before it reads a word of the body.
Link (worth indexing, Discovered)
Discovered pages are waiting for a crawl. Make them easier to reach and more obviously important: link new items from the homepage or hub pages, add "related" links between siblings, cut pagination depth (more items per page, or category hubs that split long lists). Keep them in the sitemap with an accurate lastmod. Check the server side too: if your template is slow, Google crawls less. See Google's crawl budget guide for the full list of capacity factors.
Consolidate (duplicates)
Google rates redirects and rel="canonical" as strong signals, and sitemap inclusion as a weak one. It also says: "When linking within your site, link to the canonical URL rather than a duplicate URL" (Google, consolidate duplicate URLs). In a programmatic template, all three come from the same place: the code that builds URLs. Generate the canonical, the sitemap entry and every internal link from one function, so they can't disagree.
Keep out on purpose (low-value parameter and thin URLs)
The order matters here, because noindex and robots.txt work against each other:
- Add
<meta name="robots" content="noindex,follow">(or a canonical to the clean URL), remove the URLs from the sitemap, and stop linking to them, or render filter links in a way crawlers don't follow. - Wait until Google has recrawled them and they show up under "URL marked ‘noindex’" in the Page indexing report.
- Only then, if the pattern is large, add a robots.txt
Disallowto stop the crawling.
Why wait: Google warns that "if the page is blocked by a robots.txt file or the crawler can't access the page, the crawler will never see the noindex rule, and the page can still appear in search results" (Google, block indexing with noindex). Why bother with step 3: for crawl budget, Google says "Don't use noindex, as Google will still request, but then drop the page", and recommends robots.txt for URLs you don't want crawled (crawl budget management). For facets, Google's faceted navigation page shows the pattern:
user-agent: *
disallow: /*?*sort=
disallow: /*?*tag=(Google, faceted navigation uses products=, color= and size= as its examples.)
Remove (expired and empty pages)
For pages that are gone for good, Google's advice is: "Return a 404 or 410 status code for permanently removed pages... a 404 status code is a strong signal not to crawl that URL again" (crawl budget management). On a job board this is the expired-job question. An expired job that still answers 200 with "This position has been filled" is a soft 404 waiting to happen, and it keeps occupying a slot in the crawl. We cover expired listings in more detail in job board SEO: the technical fixes from a 37k-page job site. Empty result pages ("0 jobs in Al Ain") belong in the same bucket.
Sitemap hygiene for all groups
After the actions above, the sitemap should contain only URLs that answer 200, are self-canonical, have no noindex and that you want indexed. Everything else in the sitemap is a mixed signal, and it inflates the "submitted but not indexed" count that makes the report look worse than it is.
What not to do
- Don't mass-click "Request indexing". Google says "there's a quota for submitting individual URLs and requesting a recrawl multiple times for the same URL won't get it crawled any faster" (Google, ask Google to recrawl). For Crawled pages, the status text itself says there's "no need to resubmit this URL for crawling". The decision was made on content, and a recrawl of the same content gets the same decision.
- Don't use a fresh "priority" sitemap as a cure. Splitting sitemaps by template is good for measuring. Resubmitting the same URLs in a new file doesn't change what Google thinks of them.
- Don't canonicalise with robots.txt or
noindex. Google: "Don't use the robots.txt file for canonicalization purposes", and "We don't recommend using noindex to prevent selection of a canonical page within a single site" (consolidate duplicate URLs). - Don't
noindexand robots-block a pattern at the same time. Thenoindexwill never be seen (see above). - Don't add more pages to fix indexing. Generating another 10,000 city-by-role combinations when the first 10,000 aren't indexed adds to the inventory Google is already skipping.
- Don't chase 100%. The aim is that every page you want in the index is in it, not that the excluded count is zero.
How long it takes, and how to track it
Google re-crawls on its own schedule. It says crawling after a request "can take anywhere from a few days to a few weeks" (ask Google to recrawl), and that a fix validation in the Page indexing report "typically takes up to about two weeks, but in some cases can take much longer" (Page indexing report).
Track by template, not by total:
- With per-template sitemaps, watch each sitemap's indexed vs not-indexed chart weekly.
- Re-run the grouping script on a fresh export every two to four weeks. A group that shrinks is working. A group that doesn't move after a month needs a second look.
- Watch impressions for the template's indexed pages. Indexing more pages that get no impressions isn't a win.
How SEOFix does this triage
We built this exact workflow into SEOFix because doing it by hand on a 30,000-URL job board is slow. With Search Console connected, the not-indexed triage takes every crawled page Google reports as not indexed, groups it by URL template plus parameter names, and sorts each group into worth indexing, parameter URLs, thin or empty, duplicates, or excluded on purpose. Each group gets one action: link_and_submit for Discovered pages worth indexing, improve_content for Crawled ones, keep_out for low-value patterns, canonicalize for duplicates. Groups that need work become fix tasks (INDEX_VALUABLE_NOT_INDEXED, INDEX_LOW_VALUE_INDEXABLE, INDEX_DUPLICATE_NOT_CANONICAL) that a coding agent can pick up. SEOFix won't mark these tasks "verified" after a recheck, because Google decides indexing: the triage is recomputed after the next Search Console sync instead. The Google tab explains the funnel and per-template view.
FAQ
Will "Crawled – currently not indexed" pages get indexed on their own? Google says they "may or may not be indexed in the future" (Page indexing report). Pages that stay the same usually stay where they are. Change the page or consolidate it.
Is "Discovered – currently not indexed" a crawl budget problem? Often, on large sites. Google's definition says the crawl was rescheduled because it "was expected to overload the site", and its crawl budget guide is written for sites with a large share of Discovered URLs (crawl budget management). Cut low-value URLs, speed up the template and strengthen internal links.
Should I delete pages that aren't indexed? Only the ones with no value to users: expired, empty or duplicate. Return 404/410 for those. Pages that are useful but thin should be improved, not deleted.
How many URLs can I export from Search Console? The details list for each reason is limited to 1,000 rows (Page indexing report). Filter by individual sitemaps or use the URL Inspection API (2,000 queries per day per property) for more.
Connect Search Console to SEOFix to see your not-indexed pages grouped by template, with one action per group. How to connect it.
Keep reading
"Title too long" on 28,000 pages? Fix it once, in the template
28,000 "title too long" warnings are usually one line of template code. How to find it, write a title formula with a length budget, and ship the fix in Next.js, WordPress or Laravel.
2,213 words · 10 min read
Is Cloudflare blocking Googlebot? Bot Fight Mode, AI-training blocks and how to check
Three Cloudflare settings can stop Googlebot. Here is how to tell which one is doing it, with curl, Security Events and URL Inspection, and what to change.
2,431 words · 11 min read
SEO MCP servers for site audits, compared (Ahrefs, Semrush, SE Ranking, Screaming Frog, JetOctopus, SEOFix)
Most SEO MCP servers are built for keyword and backlink data. We compared the ones that touch site audits on five things a coding agent needs, with prices and setup as of 8 October 2026.
2,089 words · 10 min read