Redirect chains: how many hops Google follows, and how to find and flatten them
Google follows up to 10 redirect hops and recommends redirecting straight to the final URL. A curl loop that finds chains in bulk, a script that flattens your redirect map, and the server configs that stop chains coming back.
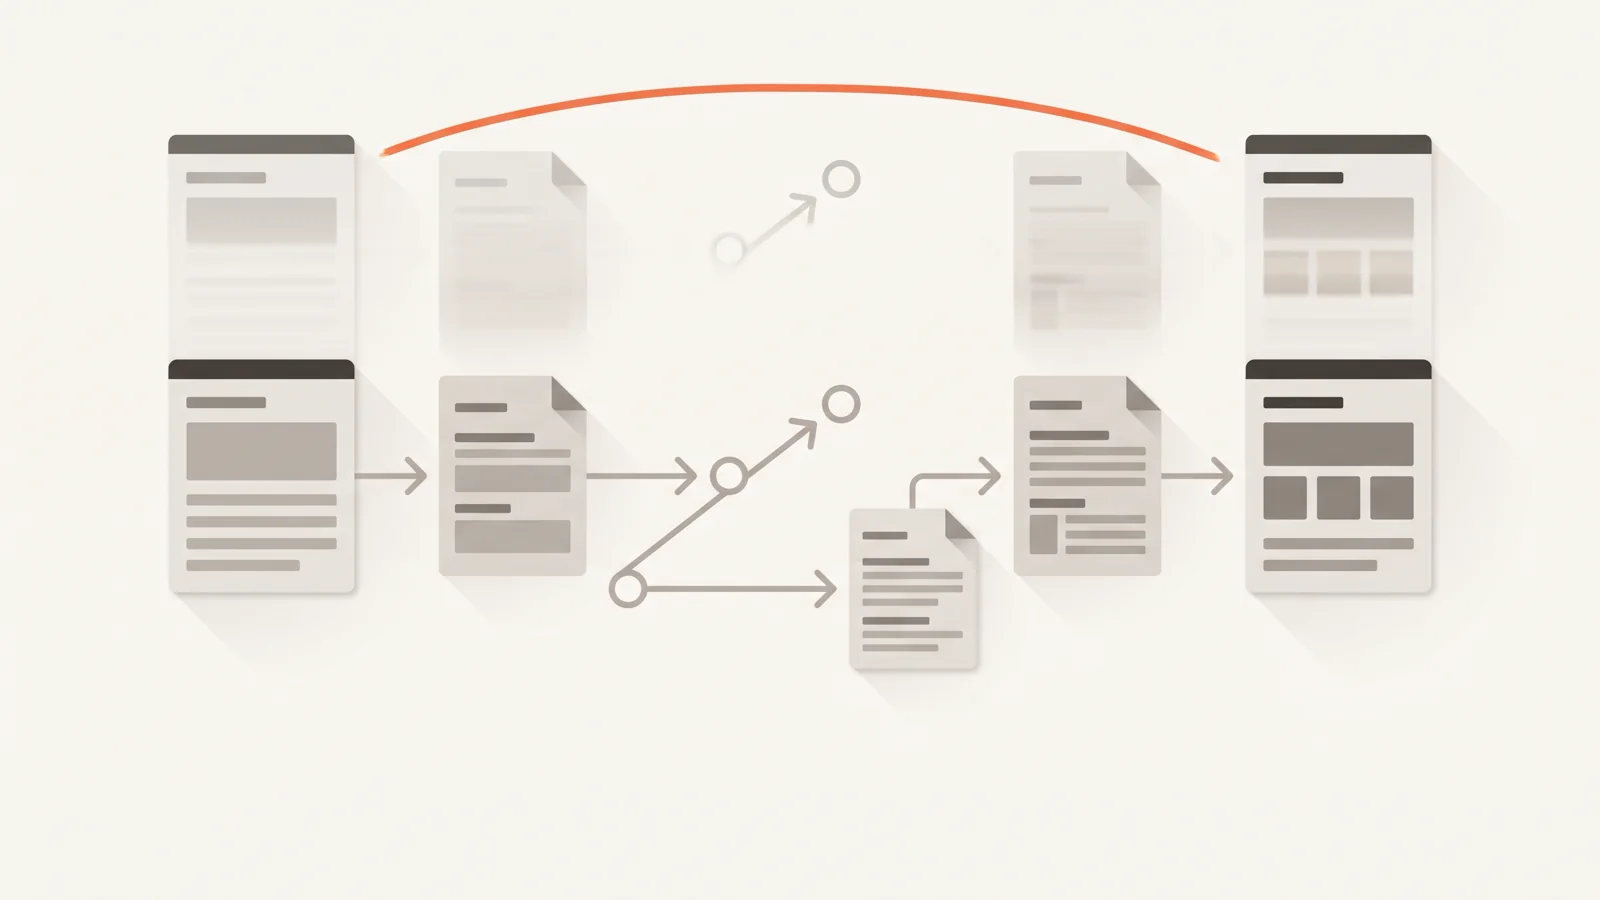
A redirect chain is a URL that redirects to another URL that redirects again before you reach a page. Google's crawlers follow up to 10 redirect hops by default, so a three-hop chain still gets indexed, but Google's own site move guide asks you to redirect "to the final destination directly" and, where that isn't possible, to keep chains "ideally no more than 3 and fewer than 5". The fix is the same on every stack: point every old URL straight at its final 200 URL in one hop, and update your links, sitemap and canonicals so nothing on your site needs the redirect at all.
This post covers finding chains in bulk and flattening them. If Search Console already shows Redirect error (a loop, more than 10 hops or a broken Location), start with Redirect error in Search Console, which has a hop-by-hop trace script. If it shows Page with redirect, that's usually fine: see Page with redirect in Search Console.
How many redirects Google follows
From Google's HTTP status code documentation, checked in November 2026:
- "By default, Google's crawlers follow up to 10 redirect hops. However, specific products' crawlers may have different limits." The same page notes that "Google Inspection Tools doesn't follow redirects."
- "Any content Google receives from the redirecting URL is ignored, and the final target URL's content is processed instead."
301and308are a strong signal that the target should be processed;302,303and307a weak one.
The site move guide adds the reason to go below 10: "Chaining redirects adds latency for users, and not all user agents and browsers support long redirect chains." HTTP itself has history here. RFC 9110 notes that an earlier version of the spec "recommended a maximum of five redirections" and that "some clients might implement such a fixed limitation."
And chains cost crawl time. Google's crawl budget guide lists "Avoid long redirect chains, which have a negative effect on crawling" among the things that help large sites.
A chain can also mix status codes. If one hop in a chain is a 302 or 307, that hop is a weak canonical signal by Google's description, even when every other hop is a 301. A chain built over years often mixes both. The 301 vs 302 vs 307 vs 308 post covers which status each framework sends by default.
Where redirect chains come from
Nobody writes a chain on purpose. They build up as rules stack:
- Host and scheme normalisation in separate rules.
http://example.com/shoesgoes tohttps://example.com/shoes(rule 1), then tohttps://www.example.com/shoes(rule 2), then tohttps://www.example.com/shoes/(rule 3, trailing slash). Three hops before any content redirect even runs. - Migrations on top of migrations. A 2019 redesign redirected
/products/shoesto/shoes. A 2023 restructure redirected/shoesto/footwear. Old backlinks to/products/shoesnow take two hops. - Two layers that each normalise. Next.js redirects
/about/to/aboutby default (trailingSlash docs). If a CDN or nginx in front forceswwwand HTTPS, a single request can pick up hops from each layer. - Slug changes in a CMS. Each rename adds a redirect from the previous slug. Rename a page three times and the first slug is three hops away unless the CMS rewrites old redirects.
- Internal links to old URLs. Not a chain on the server, but every internal link to
/shoesadds a hop that didn't need to exist.
Find redirect chains on one URL
curl -sIL prints the headers of every response it follows. Filter the status lines and Location headers:
curl -sIL http://example.com/products/shoes | grep -iE '^(HTTP|location)'HTTP/1.1 301 Moved Permanently
Location: https://example.com/products/shoes
HTTP/2 301
location: https://www.example.com/products/shoes
HTTP/2 301
location: https://www.example.com/shoes
HTTP/2 308
location: /footwear
HTTP/2 200Four hops. -I sends HEAD requests, and a few servers answer HEAD differently from GET. If the output looks odd, repeat with -o /dev/null -D - instead of -I to send GET, which is what Googlebot uses for pages.
Test the variants too: http and https, with and without www, with and without the trailing slash. Your browser has long since cached the canonical form, so you won't notice a chain that only appears on http://example.com/shoes.
Find chains across a whole site
One URL at a time doesn't scale. Feed curl a list instead. Good inputs, in order of value:
- old URLs from your redirect map (every source in
.htaccess, nginx config,next.config.jsor the CMS redirect plugin); - URLs that have backlinks (your backlink tool's "top pages" export);
- the URLs in Search Console's Page with redirect export;
- every
hrefin your own HTML (from a crawl).
This script sends one GET per hop, records the number of redirects, the final status and URL, and the status of every hop. %{num_redirects} and %{url_effective} are curl's own write-out variables. --max-redirs 10 matches Google's limit, so anything that reaches 10 and still answers 3xx is a chain Google won't finish either.
#!/usr/bin/env bash
# chains.sh urls.txt > chains.tsv
# One GET per hop. Prints: start URL, redirects, final status, final URL, status of every hop.
while IFS= read -r url; do
  curl -sL --max-redirs 10 -o /dev/null -D - \
       -w 'RESULT %{num_redirects}\t%{http_code}\t%{url_effective}\n' "$url" |
  awk -v u="$url" '/^HTTP\//{hops = hops $2 " "}
                   /^RESULT /{sub(/^RESULT /, ""); print u "\t" $0 "\t" hops}'
  sleep 0.5   # stay polite with your own server
done < "$1"
Output on a test server:
http://127.0.0.1:8765/a      3   200  http://127.0.0.1:8765/final/  301 302 301 200
http://127.0.0.1:8765/old    1   200  http://127.0.0.1:8765/final/  308 200
http://127.0.0.1:8765/about  0   200  http://127.0.0.1:8765/about   200
http://127.0.0.1:8765/loop1  10  301  http://127.0.0.1:8765/loop1   301 301 301 301 301 301 301 301 301 301 301
http://127.0.0.1:8765/gone   0   404  http://127.0.0.1:8765/gone    404
Then sort out what needs work:
# chains: two or more redirects, worst first
awk -F'\t' '$2 >= 2' chains.tsv | sort -t$'\t' -k2,2nr

# chains that contain a temporary hop
awk -F'\t' '$2 >= 2 && $5 ~ /(302|303|307) /' chains.tsv

# redirects that end in an error (a redirect to a 404 is a broken link with extra steps)
awk -F'\t' '$2 >= 1 && $3 >= 400' chains.tsv
/loop1 hit the limit while still answering 301: that's a loop, and the redirect error post covers how to break it.
Flatten the redirect map
Most chains live in a redirect map: a CSV, a CMS table or a long list of rules. The fix is to resolve every source to its final target before you deploy. This Python script reads source,target rows, follows each source through the map, writes one row per source pointing at the end of its chain, and reports loops:
# flatten_redirects.py redirects.csv > flattened.csv
import csv, sys

rules = {}
with open(sys.argv[1], newline="") as f:
    for row in csv.DictReader(f):
        rules[row["source"].strip()] = row["target"].strip()

out = csv.writer(sys.stdout)
out.writerow(["source", "target", "hops_before"])
for source in rules:
    path, seen = [source], {source}
    while path[-1] in rules:
        nxt = rules[path[-1]]
        if nxt in seen:
            print(f"LOOP: {' -> '.join(path + [nxt])}", file=sys.stderr)
            break
        path.append(nxt)
        seen.add(nxt)
    else:
        if len(path) > 2:
            print(f"chain of {len(path) - 1}: {' -> '.join(path)}", file=sys.stderr)
        out.writerow([source, path[-1], len(path) - 1])
Given this map:
source,target
/2019/shoes,/shoes
/shoes,/footwear
/footwear,/footwear/
/sale,/offers
/offers,/sale
it prints /2019/shoes,/footwear/,3 and /shoes,/footwear/,2, and reports LOOP: /sale -> /offers -> /sale instead of writing it out. Fix the loop by hand; the script can't know which page should win.
The map only knows about its own rules. Hops added by the server (scheme, host, trailing slash) aren't in it, so run chains.sh over the flattened targets afterwards. Every target should answer 200 with zero redirects. If a target shows one redirect, write the final form (usually with or without the trailing slash) into the map.
Make the server do it in one hop
Flattening the map isn't enough if the server still runs normalisation and the content redirect as separate steps. Any variant of an old URL (http, apex, trailing slash or not) should reach the final URL in one response.
nginx: one map, checked before normalisation
Put the redirect map in an nginx map and check it in every server block, including the http and apex ones, before the generic host redirect:
# http {} context
map $uri $redirect_to {
    default "";
    include /etc/nginx/redirects.map;   # lines like: /2019/shoes /footwear/;
}

server {
    listen 80;
    listen 443 ssl;
    server_name example.com www.example.com;
    # ssl_certificate ... (both names)

    # old URL: straight to the final canonical URL, whatever host or scheme was asked for
    if ($redirect_to) {
        return 301 https://www.example.com$redirect_to;
    }
    # everything else on the wrong host or scheme: one hop to the canonical host
    if ($host != "www.example.com") {
        return 301 https://www.example.com$request_uri;
    }
    if ($scheme = http) {
        return 301 https://www.example.com$request_uri;
    }
    # ... normal site config
}
Two details from the nginx docs: map "Strings are matched ignoring the case", so /Shoes and /shoes share an entry; use a regex entry with ~ if you need case-sensitive matching. And rewrite with the redirect flag answers 302 (rewrite module), so prefer return 301 for permanent moves.
Generate redirects.map from flattened.csv instead of editing it by hand, and the map can't drift back into chains.
Apache: one rule for host and scheme
Apache sites often have three separate RewriteRule blocks copied from three tutorials. Merge them. With [R=301,L] the flag docs give you an external redirect (a bare [R] is a 302):
RewriteEngine On

# content redirects first, already pointing at the final https://www URL
RewriteRule ^2019/shoes/?$ https://www.example.com/footwear/ [R=301,L]
RewriteRule ^shoes/?$      https://www.example.com/footwear/ [R=301,L]

# then host + scheme in one hop
RewriteCond %{HTTPS} off [OR]
RewriteCond %{HTTP_HOST} !^www\.example\.com$ [NC]
RewriteRule ^ https://www.example.com%{REQUEST_URI} [R=301,L]
Behind a load balancer or CDN that terminates TLS, %{HTTPS} is always off at the origin and the last rule loops. Check the forwarded protocol header your proxy sets instead.
Next.js: absolute destinations and flattened lists
Next.js redirects in next.config.js run inside the app, after any CDN rules. Two habits keep them from adding hops:
- Write destinations in their final form, including your
trailingSlashsetting. With the default (no trailing slash), a destination of/footwear/triggers a second redirect to/footwear. - Generate the list from the flattened CSV at build time instead of appending rules by hand.
// next.config.js
const fs = require("fs");

const rows = fs.readFileSync("./redirects/flattened.csv", "utf8").trim().split("\n").slice(1);

module.exports = {
  async redirects() {
    return rows.map((line) => {
      const [source, destination] = line.split(",");
      return { source, destination, permanent: true }; // 308
    });
  },
};
The Next.js redirecting guide notes that redirects "may have a limit on platforms. For example, on Vercel, there's a limit of 1,024 redirects", and suggests handling larger maps in Proxy with a lookup. The same rule applies there: look up the final target and answer once.
Update the things that point at redirects
A flat redirect map still costs one hop for every request that uses it. Most of those requests come from your own site, and those you control:
- Internal links. Replace links to old URLs with the final URL. A crawl that records the link source makes this a find-and-replace per template. See broken internal links for the template-level approach, which works the same for links to redirects.
- XML sitemaps. List only final
200URLs. A sitemap full of redirects is the most common reason for a long Page with redirect list. - Canonical and hreflang tags. A canonical pointing at a URL that redirects asks Google to trust a URL that itself says "go elsewhere".
- Your own campaigns and emails, where the links are often hard-coded years ago.
Leave the redirects themselves in place. The site move guide says to "Keep the redirects for as long as possible, generally at least 1 year", so Google can recrawl and reassign links from other sites. Backlinks and bookmarks still need them after that; cleaning up is about removing the hops in the middle, not the redirect at the start.
How SEOFix reports chains
SEOFix doesn't follow redirects automatically: each hop is recorded and fetched as its own URL (how the crawler works). That way a full audit sees every chain among the URLs it crawls. REDIRECT_CHAIN fires when a URL takes two or more redirects to reach a URL that doesn't redirect (it follows up to 10 hops) and lists the whole chain. REDIRECT_LOOP catches the loops, and REDIRECTED_INTERNAL_LINK lists every page that links to a redirect, with the final URL to link to instead. When we audited our own 37,000-page job board, it found no chains at all, but 566 internal links that went through a redirect.
FAQ
How many redirects in a chain is too many?
Google follows up to 10, and its site move guide asks for "ideally no more than 3 and fewer than 5" when you can't avoid a chain. Aim for one hop from any old URL, and zero hops from your own links.
Do redirect chains lose PageRank?
Google doesn't publish a per-hop loss. What it does document is that only the final URL's content is processed, that temporary hops are a weak canonical signal, and that long chains hurt crawling. That's enough reason to flatten them.
Does Search Console show redirect chains?
Not directly. A chain that ends in a working page usually shows up as Page with redirect for the first URL. A chain over the limit shows as Redirect error. Google's inspection tools don't follow redirects, so a live test of the old URL reports the redirect itself, not the page at the end.
Should I remove old redirects once the chain is fixed?
No. Remove the intermediate hops by pointing each source at the final URL. Keep the redirect from each old URL; backlinks and bookmarks still use it.
SEOFix crawls your site hop by hop and lists every redirect chain, loop and internal link to a redirect, grouped by the template that produces them. Your first audit is free (up to 500 pages, no card).
Keep reading
Meta description length: what Google shows, when it rewrites, and how to write them by template
Google sets no length limit for meta descriptions and often writes its own snippet anyway. What Google documents, a practical length budget, and how to generate good descriptions by template.
1,659 words · 8 min read
Soft 404 in Search Console: what triggers it and the fix for each case
Google reports a soft 404 when a page answers 200 but looks empty or like an error. Here is how to tell a real missing page from a thin template, and what to change in each case.
2,219 words · 10 min read
Does Google crawl JavaScript? How rendering works in 2026 and what still breaks
Google renders JavaScript in an evergreen Chromium, usually within seconds. Pages still drop out because of blocked files, hash routes, noindex in the HTML, 2MB cut-offs and soft 404s. How to check each one.
2,387 words · 11 min read