Crawl budget: when it matters by Google's own threshold, and what actually helps
Most sites don't have a crawl budget problem. Google's own threshold, the three signs that you might, the URL waste that eats crawling on big sites, and why noindex and Crawl-delay don't help.
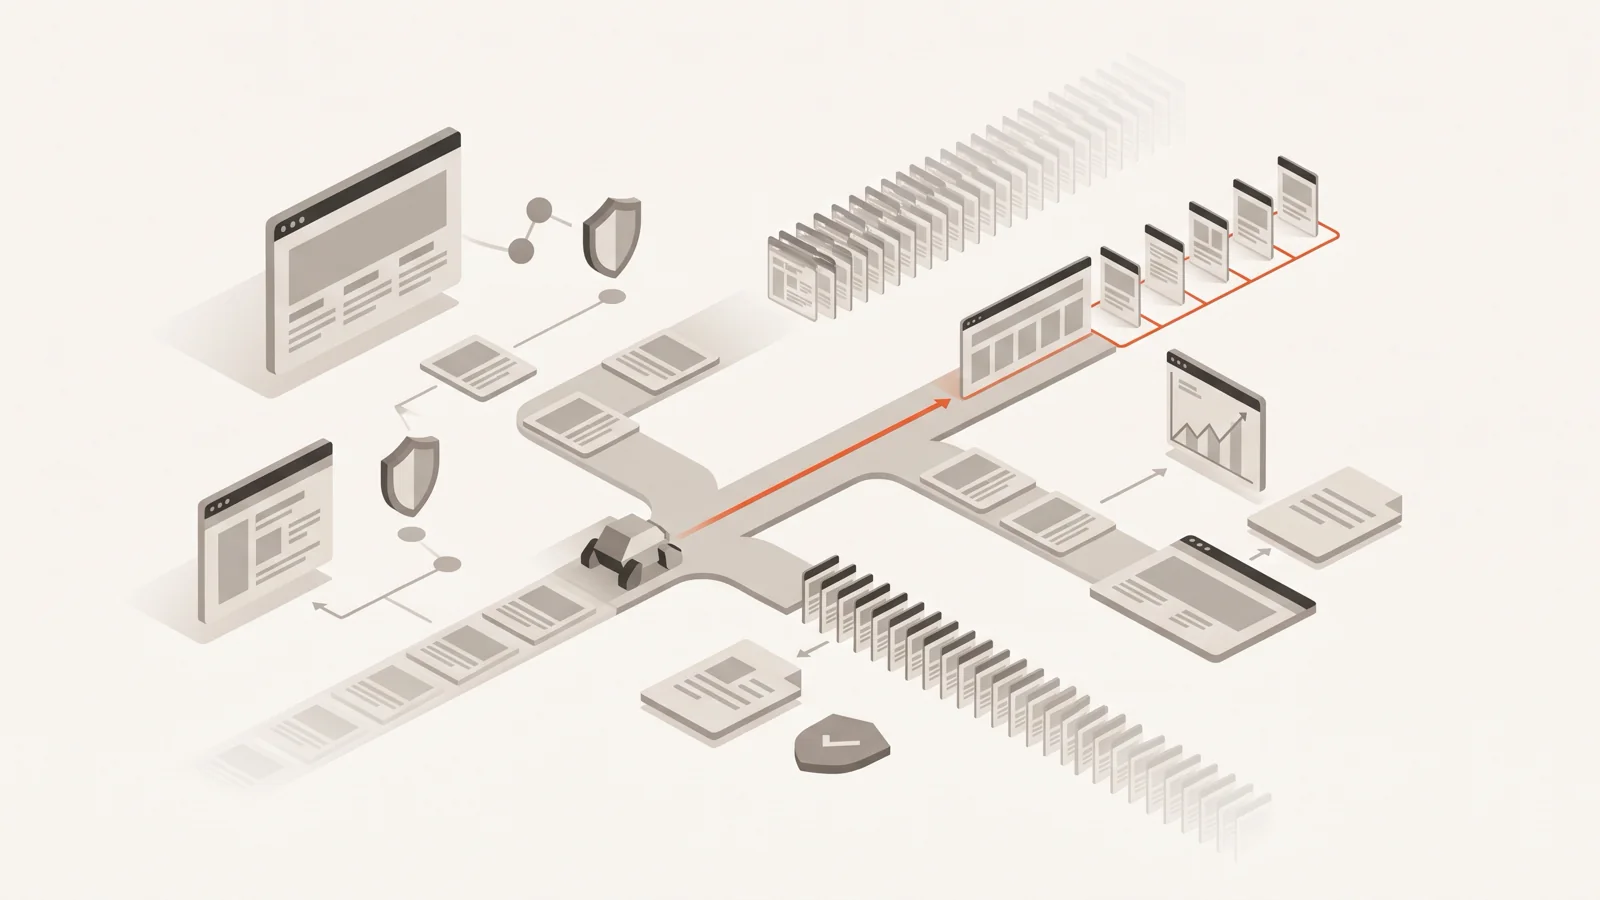
Crawl budget only matters for big sites that change quickly. Google's crawl budget guide is written for "Large sites (1 million+ unique pages) with content that changes moderately often (once a week)", "Medium or larger sites (10,000+ unique pages) with very rapidly changing content (daily)", and "Sites with a large portion of their total URLs classified by Search Console as Discovered - currently not indexed" (Google, Optimize your crawl budget, checked 2 November 2026). Google adds that these "are not exact thresholds". If your new pages get crawled the day they go live, you don't have a crawl budget problem, and the guide says so: "you don't need to read this guide."
If you are above those lines, the fix is rarely "get Google to crawl more". It's usually "stop making Google crawl URLs you don't care about": filter combinations, parameter duplicates, soft 404s, redirect chains. Below: how Google defines crawl budget, how to check whether you have a problem, what wastes it, and the popular fixes that don't work.
What crawl budget is
Google defines a site's crawl budget as "the set of URLs that Google can and wants to crawl". Two things decide it (crawl budget guide):
- Crawl capacity limit ("hostload"): how much crawling your server can take. It "limits the total amount of time your server spends holding connections open for Google, factoring in both the number of parallel connections and their duration." It goes up when "response times (including latency and Time-to-First Byte) remain stable or improve", and down when the site slows down or returns
5xxerrors or429. - Crawl demand: how much Google wants to crawl. For Googlebot it depends on "a site's size, update frequency, page quality, and relevance, compared to other sites." The factors you can influence are perceived inventory (the URLs Google knows about), popularity and staleness.
Three details from the same guide that change how you think about it:
- A site is a hostname. "https://www.example.com/ and https://code.example.com/ are treated as separate sites and have separate crawl budgets."
- Capacity is shared across Google's crawlers. "High demand from one crawler can reduce the capacity available for others." AdsBot and the Shopping crawler draw from the same pool as Googlebot.
- Low demand caps crawling even with spare capacity. "Even if the crawl capacity limit isn't reached, if crawl demand is low, Google will crawl your site less." A fast server alone won't get thin pages crawled.
Perceived inventory is the one Google calls "the factor that you can positively control the most". If many known URLs are duplicates or junk, "this wastes a lot of Google crawling time on your site."
How to tell whether you have a crawl budget problem
Size alone doesn't prove anything. A 2-million-page site with clean URLs and a fast server can be fully crawled; a 20,000-page shop with unbounded filter URLs can't. Check these three things.
1. Are new and updated pages crawled quickly?
Pick 10 pages published last week and run them through URL Inspection in Search Console. If "Last crawl" is within a day or two of publishing, crawling isn't your bottleneck. If they show "URL is unknown to Google" or haven't been crawled after weeks, keep going.
2. What does the Crawl Stats report say?
Search Console → Settings → Crawl stats. It's "available only for root-level properties" (Crawl Stats report help). Look at:
- Host status. The worst status means Google "encountered at least one significant crawl availability issue in the last week", and the details split it into robots.txt fetching, DNS resolution and server connectivity. A server problem is a capacity problem, and it comes before anything else.
- Average response time. Rising response time lowers the capacity limit. If it climbed while total requests fell, your server is the constraint.
- By response. A large share of
301,404or5xxresponses is crawling spent on URLs that aren't pages. - By purpose. "Discovery" is a URL Google never crawled before, "Refresh" a recrawl. Google says that after adding a lot of content or submitting a sitemap "you should ideally see a bump in discovery crawls".
3. Where does Googlebot go?
The report shows samples. Your access log shows everything. Count Googlebot requests by top-level section, and how many of them carry a query string:
# Googlebot requests per first path segment, busiest first
grep 'Googlebot' /var/log/nginx/access.log \
  | awk -F'"' '{split($2, r, " "); print r[2]}' \
  | cut -d/ -f2 | cut -d'?' -f1 | sort | uniq -c | sort -rn | head -20

# share of Googlebot requests with a query string
grep 'Googlebot' /var/log/nginx/access.log \
  | awk -F'"' '{split($2, r, " "); print (index(r[2], "?") ? "params" : "clean")}' \
  | sort | uniq -c
If /search, /filter or parameter URLs take half of Googlebot's requests while your product or job pages wait, that's your answer. Anyone can send a Googlebot user agent, so for a serious analysis verify the IPs with a reverse DNS lookup: the name should end in googlebot.com, google.com or googleusercontent.com, and a forward lookup of that name should return the same IP (Google, verify Googlebot):
host 66.249.66.1
# 1.66.249.66.in-addr.arpa domain name pointer crawl-66-249-66-1.googlebot.com.
host crawl-66-249-66-1.googlebot.com
# crawl-66-249-66-1.googlebot.com has address 66.249.66.1
A large Discovered – currently not indexed count in the Page indexing report is the third signal on Google's list. That status has more than one cause; Discovered – currently not indexed walks through telling a crawl capacity problem from a demand problem.
What wastes crawl budget
These are the patterns that inflate perceived inventory. They're also what Google's best practices target.
| Waste | Why Google keeps crawling it | Fix |
|---|---|---|
| Faceted navigation and sort orders | Every filter combination is a new URL | robots.txt Disallow on the parameters, or 404 for empty combinations |
Duplicate URL variants (http/https, www, trailing slash, tracking parameters) | Each variant is a separate URL to Google | One redirect per variant, canonicals, clean internal links |
| Soft 404s | They answer 200, so "soft 404 pages will continue to be crawled, and waste your budget" | Return a real 404 or 410 |
| Redirect chains | Each hop is another request; Google says chains "have a negative effect on crawling" | Redirect straight to the final URL |
| Internal links to redirects | Googlebot fetches the old URL, then the new one | Link to the final URL |
Removed pages answering 200 or 302 | Nothing tells Google to stop | 404 or 410 |
Faceted navigation is usually the biggest one. Google's faceted navigation guide describes the cost plainly: crawlers "will typically access a very large number of faceted navigation URLs before the crawlers' processes determine the URLs are in fact useless", and "if crawling is spent on useless URLs, the crawlers have less time to spend on new, useful URLs." Its recommended robots.txt:
user-agent: Googlebot
disallow: /*?*products=
disallow: /*?*color=
disallow: /*?*size=
allow: /*?products=all$
If you do want some filtered pages indexed, the same guide asks you to keep filter order fixed in the URL, use & as the separator, and return 404 "when a filter combination doesn't return results".
Duplicate host and slash variants are covered in their own posts: www vs non-www and HTTP to HTTPS and trailing slashes. For chains, see redirect chains.
What helps
In the order we'd do them on a large site:
1. Shrink the URL inventory. Block crawl traps with robots.txt, consolidate duplicates, return 404 or 410 for removed pages. Google: "a 404 status code is a strong signal not to crawl that URL again." Blocked URLs, by contrast, "will stay part of your crawl queue much longer, and will be recrawled when the block is removed."
2. Make pages fast to serve. Capacity follows response time. Uncached server renders of long-tail pages are the usual weak spot: they're exactly what crawlers request and what your cache doesn't hold. Our own crawler incident on a 2-core Next.js server shows how quickly that adds up.
3. Support conditional requests. Google's guide recommends supporting 304 Not Modified: "If a page hasn't changed since Google last crawled it, returning a 304 code tells Google to reuse the cached version." A 304 answers a conditional request carrying If-None-Match or If-Modified-Since and has no body (MDN, 304). Test it:
URL=https://www.example.com/jobs/some-listing
ETAG=$(curl -s -D - -o /dev/null "$URL" | awk 'tolower($1)=="etag:" {print $2}' | tr -d '\r')
curl -s -o /dev/null -w '%{http_code}\n' -H "If-None-Match: $ETAG" "$URL"
# 304 = supported; 200 = the page is re-sent in full every time
If you get 200, check whether the page sends an ETag or Last-Modified at all. A server-rendered page whose HTML contains a timestamp, a CSRF token or a per-request nonce changes on every request, so any ETag computed from the body changes too.
4. Keep sitemaps accurate. Google "reads your sitemap regularly", and recommends <lastmod> for updated content. A lastmod that changes on every build teaches Google to ignore it; sitemap lastmod covers how to send dates Google trusts.
5. Link to what matters. Popularity drives demand. Pages with no internal links get discovered late and recrawled rarely.
What doesn't help
noindex on crawl traps. Google is direct about it: "Don't use noindex, as Google will still request, but then drop the page when it sees a noindex meta tag or header in the HTTP response, wasting crawling time." noindex controls indexing, not crawling. Noindex vs disallow has the decision table.
robots.txt as a temporary shuffle. "Don't use robots.txt to temporarily reallocate crawl budget for other pages." Google "won't shift this newly available crawl budget to other pages unless Google is already hitting your site's crawl capacity limit." Block what you never want crawled, and leave it blocked.
Crawl-delay. Google doesn't read it; its robots.txt parser supports user-agent, allow, disallow and sitemap only (robots.txt spec).
Mass "Request indexing". It's a per-URL tool with an unpublished daily quota, not a way to raise crawling across a site. See request indexing limits.
How to get more crawl budget
Google lists two ways (crawl budget guide):
- Add server resources, if Google can't crawl because of your capacity. The sign is "Hostload exceeded" in the URL Inspection tool.
- Improve content quality. For Google Search, crawl resources factor in "popularity, overall user value, content uniqueness, and serving capacity."
That second point is why a site with 500,000 near-identical programmatic pages can have a fast server, a clean URL structure and still see most pages sit in "Discovered". Demand is low because the pages don't look worth crawling. Crawled – currently not indexed on programmatic SEO covers that side.
Finding the waste with a crawler
Server logs show where Googlebot goes. A crawl of your own site shows why: which templates link to parameter URLs, which internal links hit redirects, which pages are duplicates. SEOFix reports internal links that go through a redirect, redirect chains and loops, duplicate and near-duplicate pages, and sitemap URLs that aren't 200 (links and redirects checks, indexability checks). It also practises point 3 on itself: on repeat audits it sends your pages' stored ETag and Last-Modified back, and a page that answers 304 is not downloaded again (comparing audits).
FAQ
Does crawl budget affect rankings? Not directly. Google's guide notes that "not every page that is crawled will necessarily be indexed." Crawling is a precondition: a page Google hasn't crawled can't be indexed with its current content. More crawling of the same pages doesn't improve their ranking.
My site has 5,000 pages. Should I worry? By Google's own numbers, no, unless new pages take weeks to get crawled. If they do, look at server errors, response time and internal links before blaming crawl budget.
Are subdomains counted together? No. Each hostname has its own crawl budget, per Google's definition of a site.
SEOFix finds the redirect chains, duplicate URLs and internal links to redirects that waste crawling on large sites. Your first audit is free, up to 500 pages.
Keep reading
Next.js SEO checklist for the App Router: 14 technical checks with code and curl
Fourteen checks for a Next.js App Router site, each with the code that gets it right and the curl command that proves it, including the streaming behaviours that turn 404s into 200s and move canonicals into the body.
1,690 words · 8 min read
JobPosting schema: required fields, validThrough and the errors that cost you Google Jobs
The five properties Google requires on a job page, the recommended ones worth adding, how validThrough and expired jobs work, and the Search Console policy messages job sites run into most.
2,098 words · 10 min read
Sitemap couldn't fetch in Search Console: how to find the cause and fix it
Couldn't fetch means Google never received the sitemap file itself. How to reproduce the fetch with URL Inspection and curl, and the fix for each cause: wrong URL, robots.txt, firewall, timeouts, HTML instead of XML.
1,939 words · 9 min read